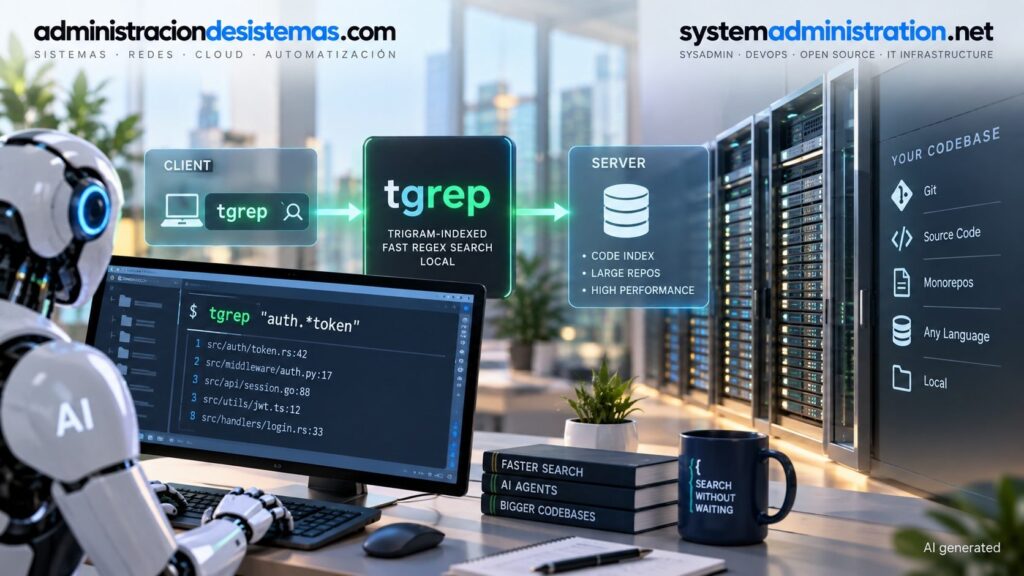
Microsoft has developed tgrep, a code-search tool designed to reduce the time AI coding agents spend repeatedly scanning large repositories. The project combines a trigram index with a background server and is integrated with GitHub Copilot CLI, where it can be used automatically for sufficiently large Git repositories.
The keys to tgrep in 30 seconds
- tgrep uses a 3-byte trigram index to narrow searches before reading files.
- Its client/server architecture keeps the index available between searches.
- In Microsoft’s benchmark, a gecko-dev repository search took 643 ms with tgrep versus 33,4 s with ripgrep on macOS.
- GitHub Copilot CLI can automatically select tgrep for large repositories when the required conditions are met.
- The project is available as open source under the MIT licence.
The difference matters most in repositories containing hundreds of thousands of files. Traditional text search tools such as ripgrep are already fast, but an AI coding agent can issue many searches during a single task. Repeating filesystem scans can therefore become a noticeable part of the time needed to complete a request.
tgrep approaches the problem differently. Instead of starting from the filesystem for every query, it maintains an index of the trigrams found in the repository. A trigram is a sequence of three consecutive bytes. When a search arrives, the index can identify files that contain the relevant sequences and reduce the amount of data that needs to be examined.
The project comes from Microsoft and is available on GitHub. Its documentation describes it as a trigram-indexed grep implementation with a client/server architecture. The server maintains the index while clients send searches to it, allowing subsequent queries to reuse information that has already been generated.
Why tgrep can be much faster on large repositories
The biggest difference appears when the repository is large enough for filesystem traversal to become expensive. Microsoft’s published benchmark uses gecko-dev, the Mozilla Firefox source repository, with 387.841 files and 122 search queries.
On macOS, the benchmark reports an average of 33.401,8 milliseconds for ripgrep, compared with 643,0 milliseconds for tgrep. That corresponds to a reported speed-up of 51,9 times for that test.
The figures vary depending on the operating system and repository. On Windows, the same gecko-dev benchmark reports 17.841,2 milliseconds for ripgrep and 462,6 milliseconds for tgrep. On Linux, the measurements are 1.194,9 and 162,4 milliseconds respectively.
That does not mean tgrep is always faster. The published results include cases where the difference is much smaller, and at least one benchmark shows ripgrep ahead. The advantage is therefore closely tied to the workload, repository size and environment rather than being a universal replacement for existing search tools.
The design also explains why the first search is not the whole story. tgrep can build and maintain its index in the background, while later queries can use that persistent data. A filesystem watcher keeps track of changes so that the index can be updated as files are modified.
This is particularly relevant to coding agents. An agent may search for a function, inspect references, look for configuration values and then repeat related searches after making changes. With a conventional search process, each operation can involve another traversal of the repository. With tgrep, the server can keep the repository’s search information ready for the next request.
How the architecture works
The project separates the search client from the process responsible for maintaining the index. The server exposes a TCP interface using JSON-RPC, while the index itself is stored on disk and can be memory-mapped.
The architecture includes components such as LiveIndex and HybridIndex. The former deals with current repository changes, while the latter combines indexed information with the state of files that may have changed since the index was created.
Keeping the index current is important because a code repository can change constantly while an AI agent is working. tgrep therefore includes filesystem monitoring and reconciliation mechanisms intended to keep searches aligned with the current contents.
The approach is different from simply replacing one search command with another. The main change is that search becomes a persistent service rather than an isolated operation. That distinction is useful for AI agents because their workflows often involve many searches over the same repository during a relatively short period.
GitHub has already incorporated the technology into GitHub Copilot CLI. Its documentation says tgrep can be enabled with the USE_TGREP environment variable and that Copilot CLI can automatically switch to it inside Git repositories when the repository meets its platform-specific file-count threshold and other conditions.
The integration is aimed particularly at large monorepositories, where scanning the entire working tree repeatedly can become costly. GitHub has also documented the move towards tgrep for large monorepos in its Copilot CLI updates.
For developers, the practical effect is less about changing how a search is written and more about reducing the amount of time spent waiting for the agent to locate information. The underlying search syntax remains familiar, while the index and server handle much of the work behind the scenes.
tgrep is also open source under the MIT licence, which means its implementation is available for inspection and reuse under that licence. The project documentation includes its architecture, benchmarks and guidance for agents working with the repository.
The broader technical point is straightforward: as AI coding agents perform more operations inside increasingly large repositories, the cost of repeatedly reading the same filesystem becomes more relevant. Persistent indexing is one way to reduce that cost. The benchmark results published by Microsoft show that the difference can be substantial in some large-repository workloads, although the results also show that performance depends on the particular environment and search set.
Preguntas frecuentes
¿Qué es tgrep?
tgrep es una herramienta de búsqueda de código desarrollada por Microsoft que utiliza un índice basado en trigramas y una arquitectura cliente/servidor para acelerar búsquedas repetidas en repositorios grandes.
¿Cuánto más rápido es tgrep que ripgrep?
En el benchmark publicado para gecko-dev en macOS, tgrep registró 643,0 ms frente a 33.401,8 ms de ripgrep, una diferencia de 51,9 veces en esa prueba concreta.
¿GitHub Copilot CLI utiliza tgrep?
Sí. GitHub Copilot CLI integra tgrep y puede seleccionarlo automáticamente en determinados repositorios Git grandes, según las condiciones y umbrales definidos por la herramienta.
¿Es tgrep de código abierto?
Sí. El proyecto está publicado en GitHub bajo la licencia MIT.